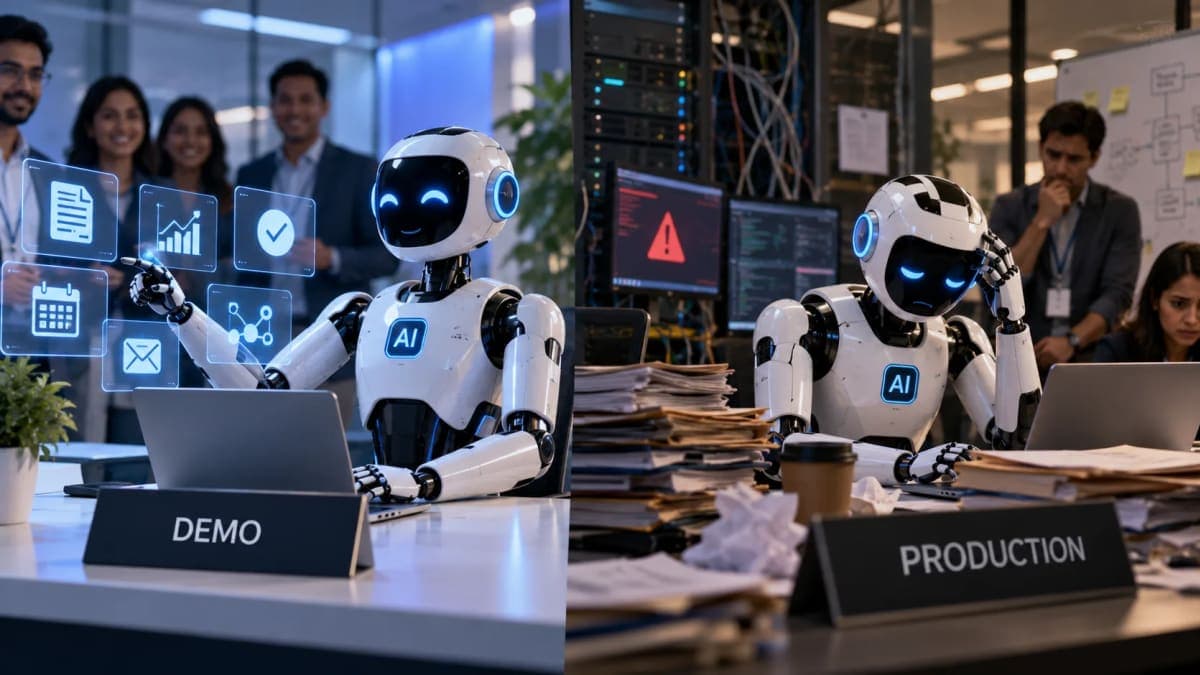
An AI agent can produce an impressive demonstration in an afternoon.
Give it a controlled dataset, a clearly defined task and access to a handful of tools, and it may research information, update records, generate documents or complete a workflow with remarkably little human involvement.
Then the company tries to put it into production.
Suddenly the agent encounters outdated customer records, conflicting permissions, legacy software, unexpected user requests, compliance requirements and situations its developers never included in the demonstration.
Its cost changes with usage.
Its behaviour can vary between runs.
And when something goes wrong, the company needs to answer a question that rarely appears in a polished demo:
Who is accountable for what the agent just did?
This gap between an agent that works and an agent an enterprise is prepared to trust with real work has become one of the defining problems of the agentic-AI boom.
Gartner forecast in 2025 that more than 40% of agentic-AI projects would be cancelled by the end of 2027, citing escalating costs, unclear business value and inadequate risk controls.
More recent evidence suggests the challenge has not disappeared.
But the explanation is increasingly clear: the model itself is often only one component of the production problem.
First, the failure statistics need some perspective
Claims that “most AI agents fail” are appearing increasingly frequently.
They need careful interpretation.
Gartner reported in January 2026 that at least 50% of generative-AI projects had been abandoned after proof of concept by the end of 2025, with poor data quality, inadequate risk controls, rising costs and unclear business value among the reasons.
That statistic covers generative AI more broadly. It should not be presented as a measured failure rate specifically for autonomous enterprise agents.
For agentic AI, Gartner's separate forecast is that more than 40% of projects will be cancelled by the end of 2027.
Meanwhile, McKinsey reports an even wider deployment gap: nearly 90% of companies say they have invested in AI, but fewer than 40% report measurable gains. McKinsey says the difference may partly reflect projects remaining in pilots and companies applying AI to isolated tasks instead of redesigning complete workflows.
The numbers differ because they measure different things.
But they point toward the same problem:
building AI is becoming easier faster than operationalising AI is becoming easy.
A pilot gets clean data. Production gets the company’s actual data.
Consider an agent built to answer questions about customer accounts.
During development, engineers might give it a curated dataset containing clean account information, consistent fields and well-structured documents.
Accuracy looks excellent.
Production is different.
The customer name in the CRM may not match the billing system.
A contract could exist as a PDF.
An important amendment might live in an email.
Product information could be outdated.
Permissions may differ between departments.
And two internal databases might disagree about which information is correct.
An agent cannot reliably reason its way out of bad underlying information.
This is one reason Gartner identifies poor data quality as a major contributor to generative-AI projects being abandoned after proof of concept.
The production challenge is therefore often less:
“Can the model answer this question?”
and more:
“Can the enterprise reliably supply the model with the correct information, permissions and context every time?”
Those are very different engineering problems.
The second wall is integration
A useful enterprise agent rarely operates alone.
A customer-service agent may need to read CRM records, retrieve invoices, check product availability, understand company policies and potentially update a support ticket.
A finance agent may interact with an ERP system, spreadsheets, invoices, procurement tools and approval workflows.
An HR agent may need employee databases, payroll information and internal policy documents.
Every connection introduces another dependency.
Gartner specifically warns that integrating agents with legacy enterprise systems can be technically complicated, disrupt existing workflows and require expensive modifications.
This helps explain why a proof of concept can appear disproportionately easy.
The demo proves that an AI model can perform a task.
Production requires proving that an entire system surrounding the model works reliably.
AI agents introduce another problem: the same input does not always guarantee the same journey
Traditional enterprise software is largely deterministic.
If the same code receives the same inputs under the same conditions, companies generally expect the same output.
AI agents complicate that assumption.
They may reason through a problem differently, select different tools or take different intermediate steps.
Microsoft describes production agents as non-deterministic, noting that behaviour can change as models, tools and traffic patterns evolve.
That creates an unusual operational problem.
A company may test an agent successfully 1,000 times and still need to understand what happens on case 1,001 when it encounters an unfamiliar combination of circumstances.
Traditional software monitoring asks:
Did the application crash?
Agent monitoring increasingly needs to ask:
What did the agent decide to do, why did it use that tool, what information did it access, and was the final action acceptable?
That requires a different observability architecture.
Production requires measuring the journey, not just the answer
Suppose two agents both successfully issue a customer refund.
Agent A verifies the customer's identity, checks the company's refund policy, confirms the transaction and issues the correct amount.
Agent B accidentally accesses an unrelated account, ignores one approval requirement and eventually produces the same correct refund.
If evaluation looks only at the final outcome, both may appear successful.
Operationally, they are not equivalent.
Recent academic work on enterprise-agent deployment makes precisely this distinction: benchmark performance does not by itself establish deployment readiness. A production system must meet reliability requirements with acceptable human oversight and operating costs.
This means companies increasingly need to evaluate agent trajectories — the sequence of tool calls, decisions and actions between request and result — rather than simply scoring the final response.
Cost can turn a successful pilot into a questionable business case
AI-agent economics also behave differently at scale.
A conventional software workflow may execute predictable database queries and business rules.
An agent can make repeated model calls, search documents, invoke external tools, reconsider a problem and delegate work to additional agents.
Every step potentially adds cost.
A pilot processing 500 transactions can therefore look financially trivial.
A production system processing millions may not.
Gartner specifically identifies escalating costs and unclear business value among the reasons it expects many agentic-AI projects to be cancelled.
That is why the most important production metric may not be model accuracy.
It could be:
cost per successfully completed business outcome.
For a customer-service agent, that could mean cost per resolved case.
For an invoice agent, cost per correctly processed invoice.
For a sales agent, cost per qualified opportunity.
The question changes from:
“Can AI do this?”
to:
“Can AI do this reliably enough, cheaply enough and often enough to justify replacing or redesigning the existing process?”
Governance becomes harder when software can take actions
The difference between a chatbot and an agent is especially important here.
An assistant may recommend cancelling an order.
An agent may actually cancel it.
An assistant may draft an email.
An agent may send it.
An assistant may identify an incorrect payment.
An agent may be authorised to initiate a correction.
As autonomy increases, the cost of an error can increase with it.
Gartner warned in May 2026 that treating all AI agents with identical governance can itself create problems. It forecasts that 40% of enterprises will demote or decommission autonomous agents by 2027 because of governance gaps identified after production incidents.
Its argument is important: governance needs to reflect both how autonomous an agent is and what systems it can access.
An internal research agent reading public documents does not require the same controls as an agent authorised to modify financial records.
The wrong response is to put maximum controls around everything
Companies facing these risks can make the opposite mistake.
They can surround every AI application with so many approvals that automation loses much of its value.
Imagine an agent that:
finds an invoice → asks a human for permission → reads it → asks again → checks the purchase order → requests another approval → prepares a payment → waits for another person.
At some point, the organisation has created a very expensive assistant rather than an autonomous workflow.
This is why risk-tiered governance is becoming important.
Low-risk activities can operate with relatively light oversight.
Higher-impact actions require stronger permissions, evaluations, audit trails and human intervention.
The objective is not maximum autonomy.
It is the appropriate amount of autonomy for the consequences of the task.
The biggest mistake may be automating a workflow that was never redesigned for AI
This is where the deployment story moves beyond technology.
McKinsey argues that many corporate workflows were created for a pre-AI world and that adding AI to individual tasks inside those workflows is unlikely to capture the technology's full productivity potential.
Its analysis of 190 US business processes found that about 60% of potential AI and automation productivity gains are concentrated in sector-specific workflows, rather than generic horizontal activities alone.
This helps explain a common pilot trap.
A company asks:
“Where can we insert an agent into our existing process?”
A more consequential question may be:
“If AI agents existed when we designed this process, would we have designed the workflow this way at all?”
Those approaches can lead to radically different systems.
The 90% pilot problem
McKinsey previously estimated that roughly 90% of function-specific or “vertical” generative-AI use cases remained stuck in pilot mode, despite broad enterprise adoption of more general copilots and chatbots.
That distinction helps explain why enterprise AI can simultaneously look ubiquitous and immature.
Employees may already use AI for writing, research, summarisation and coding.
Those applications can scale without giving AI deep authority over company processes.
An autonomous procurement agent is different.
So is an insurance-claims agent, loan-processing agent or cybersecurity agent.
The more closely AI moves toward a company's core operations, the higher the reliability threshold becomes.
The companies scaling AI are treating deployment as an operating problem
There is evidence of what more mature adoption looks like.
OpenAI's 2026 interviews with executives at companies including Philips, BBVA, Mirakl, Scout24, JetBrains and Scania found recurring patterns among organisations scaling AI.
Those included redesigning workflows, involving security, legal, compliance and IT early, building employee trust and proving that systems continue working under production pressure.
OpenAI's broader Enterprise Signals data also finds a substantial gap between typical companies and the most intensive adopters.
Organizations at the 95th percentile of AI usage were consuming 3.5 times as much AI capability per worker as typical firms, while their use of advanced agentic coding workflows was substantially higher.
That does not prove deeper AI usage causes superior financial performance.
But it suggests that mature adoption is increasingly differentiated by depth of integration, not simply whether employees have access to a chatbot.
A useful production checklist looks very different from a demo checklist
A pilot asks whether the agent can perform the task.
Before production, an enterprise needs several additional answers:
Value: Is the problem valuable enough to justify agentic AI rather than ordinary automation?
Data: Can the agent reliably access current, authoritative information?
Integration: Can it interact safely with the systems required to complete the workflow?
Reliability: How frequently does it succeed under realistic conditions, including unusual cases?
Permissions: What can the agent read, change, send or approve?
Observability: Can operators reconstruct what happened when something goes wrong?
Human intervention: Which decisions require approval, and when must the agent stop?
Cost: What is the cost per successful business outcome at production volume?
Ownership: Which person or team is accountable for the agent after launch?
Business impact: Is the system actually reducing cost, increasing speed, improving quality or generating revenue?
That is a considerably higher bar than producing an impressive demonstration.
JantaScope Analysis: The pilot-to-production gap is really a systems problem
The current enterprise-agent debate is often framed as a question of whether AI models are good enough.
That increasingly looks incomplete.
The model may be capable enough to perform the task while the organisation surrounding it is not ready to let it perform the task autonomously.
Production requires five systems to work together:
the model + enterprise data + software integrations + governance + redesigned workflow.
Weakness in any one can stop deployment.
This also explains why simply waiting for the next, more intelligent model may not solve the problem.
A better model cannot automatically clean a company's data architecture.
It cannot decide the company's risk tolerance.
It cannot determine who should approve a financial transaction.
It cannot establish regulatory accountability.
And it cannot prove that automating a particular workflow produces enough economic value to justify the cost.
The industry is therefore moving into a different phase.
The first phase of generative AI asked:
Can the model do something impressive?
The agent era increasingly asks:
Can we safely give the model enough authority to do something economically useful?
Those questions sound similar.
For an enterprise, they are worlds apart.